Data science has a delicious irony: the people who build AI models for a living are now heavy users of AI tools themselves. The best AI tools for data scientists in 2026 aren’t the models — they’re the copilots, accelerators, and force-multipliers around the models. Here’s the modern stack, from the practitioners actually shipping. The question we answer here: what are the best AI tools for data scientists.
What are the best AI tools for data scientists?
The coding layer: where AI hit hardest
Let’s start with the obvious because it’s the biggest productivity shift in data science in a decade. AI coding assistants now write the boilerplate that used to eat data scientists’ days: data loading and cleaning pipelines, pandas transformations, visualization code, scikit-learn scaffolding, SQL queries. The experienced DS workflow in 2026 looks like this: describe the analysis, let AI draft the code, review critically (this step is non-negotiable — AI-generated data code has subtle bugs), iterate conversationally.
The practitioners getting 2-3x leverage share a trait: they’re excellent reviewers. They catch the silent errors — the join that duplicated rows, the leakage between train and test, the aggregation that double-counted. AI writes code fast; senior judgment keeps it correct. Junior data scientists should be slightly nervous and mostly motivated: the ones who learn to verify rigorously are thriving; the ones who copy-paste blindly are building portfolios of impressive-looking wrong answers.
Notebooks get a brain
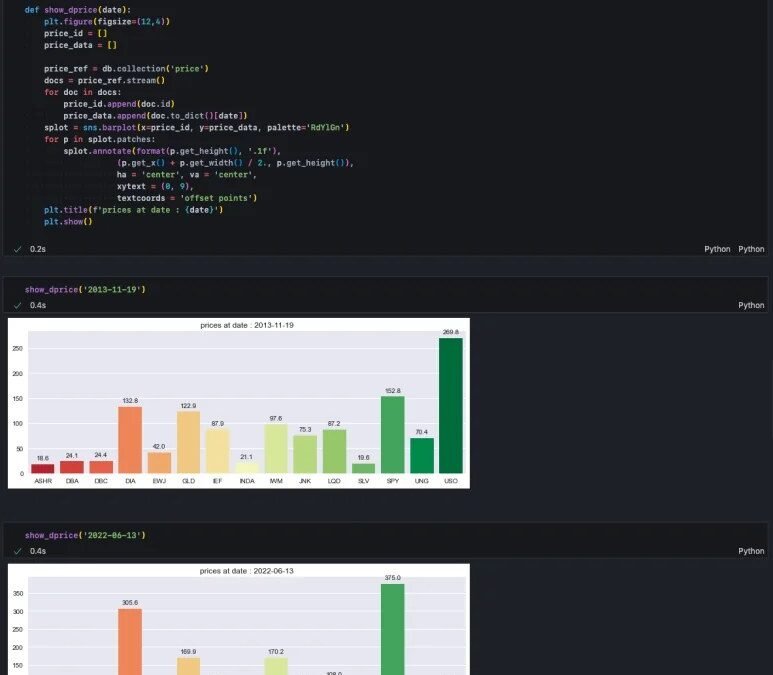
Jupyter and its successors absorbed AI natively: inline code generation, error explanation (“why did this merge produce NaNs?”), automatic visualization suggestions, and natural-language data queries. The notebook is becoming a conversation — you ask questions about your data in English, the AI writes and runs the code, you interrogate the results. It doesn’t replace statistical thinking; it removes the syntax tax on it.
AutoML and modeling accelerators
Automated machine learning matured from “toy for beginners” to “legitimate baseline generator.” In 2026, serious teams use AutoML to establish strong baselines fast, then focus human effort where it matters: feature engineering from domain knowledge, problem framing, and the last 10% of performance that automation can’t reach. The honest take: AutoML wins on standard tabular problems; novel problems still need human modelers. Know which problem you have.
Experiment tracking and MLOps
As AI-assisted data scientists run more experiments faster, the bottleneck moved to tracking: which data, which code, which hyperparameters produced which result? Modern experiment tracking with AI-assisted metadata (auto-documented runs, natural-language experiment search — “show me last month’s churn experiments with AUC above 0.8”) keeps the accelerated workflow from descending into chaos. If your team generates experiments 3x faster now, your tracking needs to be 3x better. It probably isn’t. Fix that before buying more modeling tools.
Data work: the unglamorous 80%
Everyone knows data scientists spend most of their time on data wrangling. AI tools finally attack this directly: intelligent data cleaning (suggesting fixes for inconsistencies, not just flagging them), synthetic data generation for testing and privacy-safe development, automated documentation of datasets, and natural-language interfaces for data warehouses (“show me monthly revenue by segment for the last two years” → SQL + chart). The synthetic data piece deserves attention — generating realistic test data that preserves statistical properties without exposing real customer records solves genuine privacy headaches.
Visualization and communication
The most underrated AI upgrade: turning analysis into communication. AI drafts the narrative around your findings, suggests the right chart for the message (not just the data), and helps tailor the same analysis for technical and executive audiences. Data scientists have always known that the analysis is only half the job; AI finally helps with the other half. This connects to AI for business dashboards — the handoff from analysis to decision-makers keeps getting smoother.
Building your 2026 DS stack: practical advice
- Master one AI coding assistant deeply rather than dabbling in five. The productivity comes from fluency — knowing exactly what to delegate and what to write yourself.
- Invest in verification skills deliberately: statistical review of AI-generated analysis, data validation habits, the discipline to reproduce surprising results independently.
- Automate the boring, keep the interesting. Let AI handle EDA boilerplate and standard modeling; spend your freed hours on problem framing and stakeholder conversations — the parts that determine whether your work matters.
- Learn the adjacent tools: AI for Excel for the business users you’ll collaborate with, and AI tools for market researchers if your work touches that world — the modern DS role is increasingly cross-functional.
The verification toolkit
Since AI writes so much data science code now, here’s the verification checklist senior practitioners actually use: 1. Row-count check — after every join and filter, verify row counts match expectations (the silent duplication bug is the #1 AI-generated data error). 2. Distribution sniff test — eyeball summary statistics before and after transformations; impossible values (negative ages, future dates) reveal logic errors. 3. Train-test separation audit — confirm no leakage: the model’s performance should drop slightly on truly held-out data, not collapse or stay suspiciously identical. 4. Reproduce the surprising — any unexpected finding gets re-derived independently before it’s reported. 5. Read the generated code once, fully — no skimming; the bug hides in the line you skipped. Print this, tape it to your monitor. The data scientists who verify rigorously ship work that holds up; the ones who don’t ship impressive notebooks that fall apart under scrutiny.
The through-line: OpenAI‘s models and their competitors didn’t make data scientists obsolete — they made the mechanical parts of data science cheap, which made the judgment parts more valuable. The data scientists thriving in 2026 aren’t the best coders; they’re the best thinkers who code with AI assistance. Be the thinker.